Two Claude Code sessions in the same folder will sooner or later edit the same file and undo each other's work. A worktree fixes that by giving each session its own copy of the files on its own branch. Here is where Claude Code stores worktrees, how they work, what they share with your main folder, and the small routine that makes them worth using.
This reflects Claude Code 2.1.x and its worktrees guide as of October 2026. Worktree behaviour has changed often between releases; check the guide for the current details.
The gist
Use a worktree when two Claude sessions need to work at the same time on different files. For one task, or for tasks that change the same files, stay in your normal folder.
- Treat a worktree as a separate copy of the files, not a separate computer. It keeps edits apart, but every session still shares your git history, your permission approvals and your credentials. To limit what an agent can reach, use Claude Code's sandbox (its limits on which files and network an agent can reach).
- Give each worktree one task and a name. A named session asks before it deletes anything when you exit, and the name tells you what the worktree was for.
- Prepare the project once, not each worktree. A new worktree has only the files git tracks, so
.envand installed dependencies are missing. A.gitignoreentry and a.worktreeincludefile, set up once, make every new worktree ready to use. - Merge before you remove. Removing a worktree deletes its folder, its branch and any work that isn't merged or pushed.
The picture to hold in your head
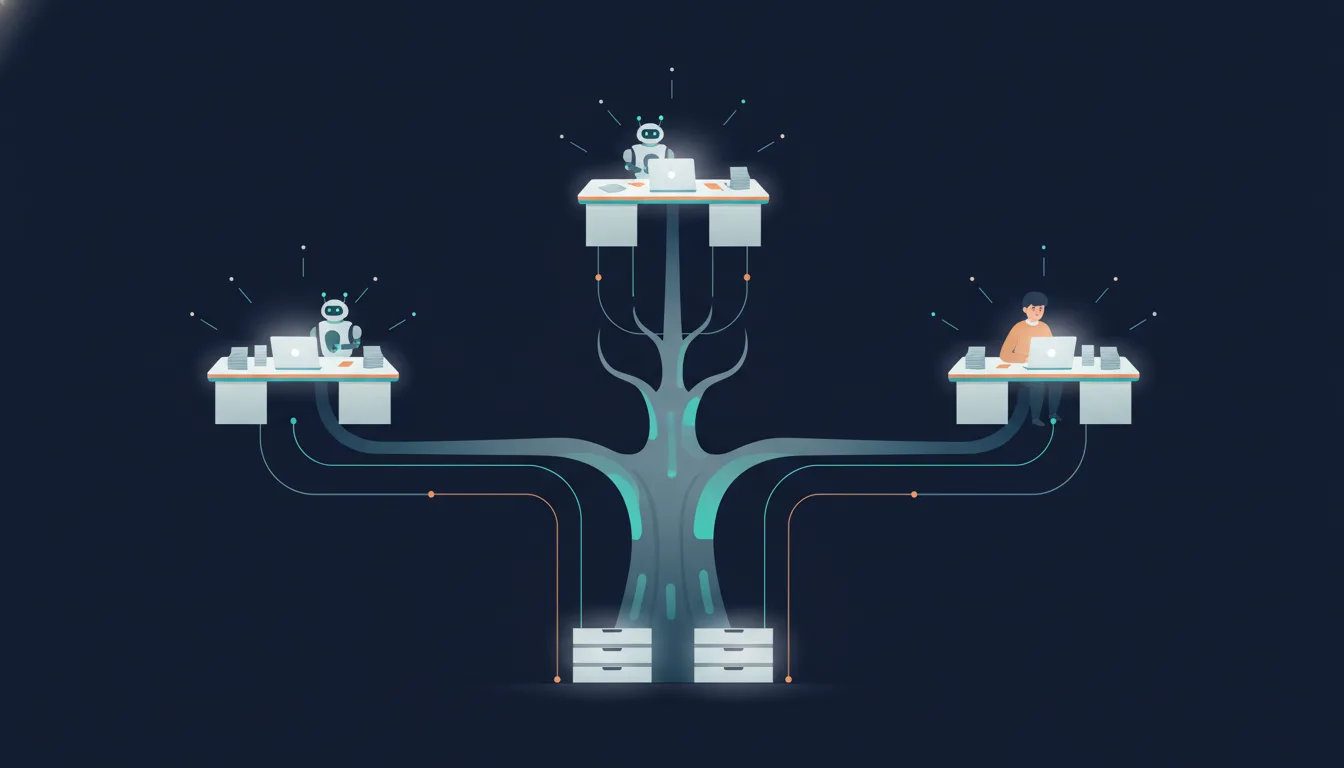
A worktree is a second folder of files, on its own branch, that shares one git history with your main folder. Each Claude Code session that runs in its own worktree edits its own files, so two sessions can work at the same time without touching each other's changes. Everything they commit goes into the same history, so you merge their work like any other branch.
The rest of this post fills in that picture: first what git itself does, then what Claude Code adds on top, and finally how to use it without leaving old folders and branches on disk.
What a git worktree is
A worktree is a plain git feature, older than Claude Code. Normally a repository has one folder of files, called the working tree, and you switch branches inside it. The files in it that git follows are the tracked files. git worktree add creates a second folder linked to the same repository, with a different branch checked out (opened) in it[1].
Git names the two kinds:
- The main worktree is the folder you got from
git cloneorgit init. There is always exactly one, and you can't remove it. - A linked worktree is each extra folder you add. A repository can have as many as you like.
A linked worktree doesn't have its own .git directory. It has a small .git file that points back to the main repository. Git keeps the details of each linked worktree in a private subfolder, .git/worktrees/<name>/, inside the main repository.
What the folders share and what they keep to themselves follows from that:
- Shared: every commit, every branch, every tag and the remote. A commit made in one worktree is visible from all the others straight away.
- Kept per worktree: the files on disk, the current branch (git calls it
HEAD), and the staging area (the list of changes prepared for the next commit, which git calls the index).
One rule matters in practice: a branch can be checked out in only one worktree at a time. Git refuses to create a worktree on a branch that another worktree already uses. Because of this rule, two sessions never commit to the same branch at the same time.
git worktree add ../project-feature-a -b feature-a   # new folder on a new branch
git worktree list                                    # main worktree first, then linked ones
git worktree remove ../project-feature-a             # only works if the folder has no changes
Where Claude Code stores its worktrees
Claude Code uses git worktree and picks the place and the branch name for you[2]. When you start a session with claude --worktree feature-auth:
- The folder is
.claude/worktrees/feature-auth/, at the root of your repository. - The branch is a new one called
worktree-feature-auth. - The starting point is your repository's default branch on the remote (the shared copy on a server such as GitHub), usually
origin/main. Claude Code downloads its latest version first if it hasn't done so in the last 24 hours. So a new worktree starts clean and does not include commits you haven't pushed yet.
If you don't give a name, Claude Code makes one up, such as bright-running-fox.
Here is what that looks like on disk, with the git side and the files side next to each other:
my-project/                      ← main worktree (branch: main)
├── .git/
│   └── worktrees/
│       └── feature-auth/        ← git's private notes about the linked worktree
└── .claude/
    └── worktrees/
        └── feature-auth/        ← the linked worktree (branch: worktree-feature-auth)
            ├── .git             ← a file, not a folder: it points back to my-project/.git
            └── src/ …           ← a full copy of the tracked files
Because the worktrees live inside your main folder, git in the main folder sees them as new, untracked files. Add .claude/worktrees/ to your .gitignore before you create the first one, or git status fills up with every file of every worktree.
Two options change these defaults:
worktree.baseRefset to"head"makes new worktrees start from your current local commit instead of the remote default branch. Use it when the work in the worktree depends on commits you haven't pushed.- A
WorktreeCreatehook (a script Claude Code runs instead of its own logic) replaces the whole creation step. You need it to put worktrees somewhere else, or to use a version control system other than git.
Three ways to start a worktree
You can start a worktree yourself, ask Claude to start one, or make a subagent (a helper agent that Claude starts for one part of the task) always use one.
- From the command line.
claude --worktree <name>(or-w <name>) creates the worktree and starts the session inside it. Run the same command with another name in a second terminal for a second session. You can also pass a pull request (PR) number in quotes,claude --worktree "#1234", and Claude Code downloads that pull request into.claude/worktrees/pr-1234. - During a session. Ask Claude to "work in a worktree". It creates one with its
EnterWorktreetool and moves the session into it. - For subagents. Ask Claude to "use worktrees for your agents", or add
isolation: worktreeto a custom subagent's settings. Each subagent then gets its own temporary worktree, so several of them can edit files at the same time. Subagent worktrees start from the same point as--worktree, the remote default branch. So a subagent doesn't see your unpushed commits unlessworktree.baseRefis"head", and it never sees changes you haven't committed.
---
name: refactorer
description: Applies mechanical refactors across many files
isolation: worktree
---

Apply the requested refactor across every affected file, then run the tests
and report the results.
The three ways differ in who decides and in how long the worktree lives:
claude --worktree | Asking Claude | isolation: worktree | |
|---|---|---|---|
| Who starts it | You | Claude, when you ask | Claude, for each subagent |
| Who chooses the name | You (or a random name) | Claude | Claude |
| How long it lives | Until you exit and choose to remove it | Until you exit and choose to remove it | Removed when the subagent finishes, if it has no changes |
| Best for | Two or more tasks you follow yourself | Moving the current task to its own folder | Many small parallel edits |
What a worktree keeps apart, and what it shares
A worktree keeps files apart. It doesn't keep anything else apart. That distinction is where most surprises come from.
Claude Code adds its own checks on top of git[2]. While a session runs in a worktree, Claude Code refuses:
- an edit to a file in the main folder;
- a shell command whose working folder is the main folder;
- a git command that is pointed at the main folder (for example with
git -C).
These checks read the command's text and the path it targets. They don't follow what a command actually writes. A copy command (cp) into the main folder, or a redirect (>, which writes a command's output into a file) such as > ../../file.txt, is not refused by them. Your normal permission rules and sandbox settings decide those commands.
Several things are shared on purpose, so you don't have to set them up again in each worktree:
| What | In a worktree |
|---|---|
| Tracked files and the current branch | Separate: its own copy |
Ignored files (.env, node_modules, build output) | Missing: not copied unless you ask |
| Commits, branches and the remote | Shared with the main folder |
| "Yes, and don't ask again" permission approvals | Shared: saved in the main folder's settings |
| Plugins installed for the project | Shared: no need to install them again |
| Skills, agents and commands that git ignores | Shared: read from the main folder |
| Your user account, credentials and network access | Shared: the same as in the main folder |
Two rows need a sentence each. First, ignored files are not copied: a worktree starts with only the tracked files, so your file of secret settings (.env) and your installed dependencies are not there until you bring them over. Second, the last row means a worktree is not a security boundary. Every session still runs as you, with your keys and your network. Use worktrees to keep parallel work tidy, and use the sandbox to limit what an agent can reach.
What happens when a session ends
When you exit a session that runs in a worktree, Claude Code checks whether removing the worktree would delete any work: changed files, new untracked files, or new commits[2]. What it does next depends on the answer.
- No work in it. For an unnamed session, Claude Code removes the folder and the branch without asking. For a named session, it asks first, so you can keep the worktree for later.
- Work in it. Claude Code asks you to keep or remove it. Keeping it leaves the folder and the branch on disk, and Claude Code prints the exact command to come back to it. Removing it deletes the folder, the branch, and every change in them.
- Runs started with
claude -p(which print one answer and exit) have no exit question, so their worktrees stay on disk until you remove them.
Subagent worktrees follow a simpler rule. Claude Code removes them when the subagent finishes with no changes. A subagent worktree that still has changes stays on disk. A regular background clean-up removes it later, but only once it is older than the cleanupPeriodDays setting (30 days by default[3]) and has no work left to lose: no changed or untracked files and no commits that haven't been pushed. The clean-up never touches a worktree you created yourself with git worktree add.
Anything the automatic rules leave behind, you remove with git:
git worktree list                                         # see every worktree
git worktree remove .claude/worktrees/feature-auth        # add --force to drop uncommitted changes
git worktree unlock .claude/worktrees/feature-auth        # if git says the worktree is locked
git worktree prune                                        # forget worktrees whose folders are already gone
How to use worktrees well
Worktrees cost a little setup each time, so they are worth it only if you follow a routine. These steps are in the order you meet them.
-
Ignore the folder once. Add
.claude/worktrees/to.gitignore, as shown earlier. -
Bring your ignored files with you. Create a
.worktreeincludefile at the root of the repository. It uses the same pattern format as.gitignore, and Claude Code copies every file that matches it and is ignored by git into each new worktree..env.env.localconfig/secrets.json -
Don't install dependencies again for every worktree. Either ask Claude to run your setup step as its first task, or link large folders from the main folder with a symbolic link (a shortcut that points to another folder), using
worktree.symlinkDirectories[3]. A link is cheap, but every worktree then uses the same folder. Do this only when the branches use the same dependencies.{"worktree": {"symlinkDirectories": ["node_modules", ".cache"]}} -
One task per worktree, with a clear name.
fix-login-redirecttells you on exit what the worktree was for;bright-running-foxdoesn't. Named sessions also ask before removing, which protects work you want to keep. -
Pick tasks that touch different files. Worktrees stop sessions from overwriting each other now. They don't stop the conflict later: if two sessions change the same lines, you resolve it when you merge the second branch.
-
Commit inside the worktree, merge from outside. Ask the session to commit on its branch, then open a pull request or merge the branch from the main folder. Merged and pushed work is safe to remove.
-
Watch the resources that git doesn't separate. Two development servers on the same port, or two test runs against the same local database, still collide. Give each worktree its own port, or run those steps one at a time.
-
Decide on exit, then check from time to time. Answer the keep-or-remove question on purpose, and run
git worktree listregularly to remove the ones you forgot.
Of these steps, the .worktreeinclude file and one task per named worktree save the most time: the first removes the "why is my .env missing" error, and the second makes every exit question easy to answer.
When a worktree is the wrong tool
A worktree adds a folder, a branch and a setup step. That cost is wasted in these cases:
- There is only one task. One session in your normal folder is simpler.
- The tasks change the same files. You only move the conflict to merge time. Do them one after the other.
- The repository has no commits yet. A worktree starts from a commit, so
claude --worktreefails until the first one exists. - Setting up a copy is slow or large, and linking folders isn't safe for your project. A second session that only reads code, or a subagent that only searches, needs no worktree.
- You want to limit what an agent can do. That is the sandbox's job, not the worktree's.
For everything else — a feature in one terminal and a bug fix in another, or a batch of independent edits split across subagents — a worktree is the cheapest way to let two Claude sessions work at the same time without one undoing the other.