I had seventeen live websites on seven domains, most of them on GitHub Pages, and no way to know whether anyone had ever visited them. Choosing a tracker turned out to depend on consent law and ad blockers much more than on features.
Free plans, blocklists and prices change quickly. Everything here describes the situation in September 2026, so check the current terms before you copy this decision. The legal points are my reading of published guidance, not legal advice.
Seventeen sites and no data
My projects folder has 26 directories. Seventeen of them are live public websites, on seven root domains: pearpages.com, perepages.com, pages.ninja, soms.cat, igarrotxa.com, trainingaccio.com and bitepals.com. Sixteen are served by GitHub Pages. GitHub Pages sends the files to the browser and tells you nothing about who asked for them. The seventeenth is a Next.js app on Vercel. Only one of the seventeen had any tracking at all: this blog, with a Google Analytics 4 (GA4) property behind a consent banner.
So for sixteen sites I knew nothing. Not "low traffic", not "fewer visits than before". Nothing, because nobody had ever measured anything.
The question I wanted to answer is small and simple: did anyone look at this project, and is the number growing? I didn't need funnels, groups of users or ad attribution. I needed one number per site per month, and a line that goes up or doesn't.
A small question doesn't mean an easy choice of tool, though. The number and the variety of the sites limit the choice much more than the question does.
What seventeen sites need from a tracker
Four requirements follow directly from the situation. It's worth writing them down before looking at any product page:
- Seventeen sites, at zero cost. These are hobby projects and two small business sites. A price per site, or a free plan that stops at fewer than ten sites, rules a tool out.
- One dashboard. Nobody will log in to seventeen dashboards every month to see if anything is growing. The whole point is one page that lists every hostname.
- No consent banner. The sites are built with four different tools: Astro, plain HyperText Markup Language (HTML) files, Docusaurus and Next.js. A banner would have to be designed, built, stored and tested in each of them before the first number appeared. That would be by far the biggest part of the work, and it adds nothing to the measurement.
- Numbers that aren't wrong without anyone noticing. A tracker that misses half the visitors, without telling you, answers a different question from the one you asked.
A product page answers the first two. The last two decide the choice, and each one gets its own section below. Both depend on how the tracker reaches the visitor's browser, not on the features you can compare on a product page.
The consent banner is about storage, not privacy
This fact changes the whole comparison: the law that causes cookie banners doesn't care whether your data is anonymous. It cares whether you stored or read something on the visitor's device.
The rule is Article 5(3) of the European Union's (EU) ePrivacy Directive, Directive 2002/58/EC, as changed in 2009. In Spain it is Article 22.2 of Ley 34/2002, the Ley de Servicios de la Sociedad de la Información (LSSI, the Spanish law on information-society services). It covers "storing information or gaining access to information stored in the terminal equipment of a subscriber or user". That's all it covers. What the stored data contains is a different question, and data-protection law handles it. Storage alone is what makes the rule apply.
This is why "we turned on IP anonymisation" doesn't remove the banner. Anonymising GA4 doesn't stop it from writing a _ga identifier into the browser, and that write is the act the law regulates. The banner is still required, whatever privacy setting Google offers.
There is an exception, and it is narrow. Spain's data protection authority, the Agencia Española de Protección de Datos (AEPD), published a guide on cookies for audience-measurement tools in January 2024. It explains when analytics can store data without asking for consent. All four conditions must be true:
- The purpose is only to measure the audience of that one site or app.
- The data is processed only on behalf of the site's owner, and produces only anonymous statistics.
- The data is not combined with other data and not sent to anyone else.
- It does not allow following a person across different sites or apps. The guide says clearly that this rules out any tool that uses the same identifier on several sites, for example a cookie on a third-party domain that all the sites load.
Condition four decides this project. One GA4 property that covers seventeen domains is exactly the cross-site tracking that the exception rules out. The thing I wanted most, one dashboard for everything, is what stops the obvious tool from using the exception.
Two more details matter later. First, not needing consent doesn't mean not needing to inform. The guide still requires you to explain the measurement in the privacy policy, to keep identifiers for about thirteen months at most without renewing them automatically, and to keep the collected data for twenty-five months at most. Second, the simplest position is not to use the exception at all. It's to never trigger Article 5(3): store nothing and read nothing.
That leaves the fourth requirement: whether the numbers you do collect are real.
What ad blockers do to a site with twenty visits a month
On a site with a lot of traffic, missing 30% of the visits is annoying, but you can still read the trend. On a site with twenty visits a month, missing 30% makes the data useless, because you can no longer tell "nobody came" from "everybody blocked the tracker". Those were exactly the two cases I wanted to tell apart.
The visitors of these projects are developers, and developers block the most. Plausible measured one popular post with two trackers. Google Analytics missed 58% of the visitors who came from Hacker News and Reddit. It missed 68% on desktop computers, 82% on Linux and 88% on Firefox. Plausible's lower general estimate is that more than 25% of visitors block trackers on technical sites, and fewer than 10% on lifestyle sites. Even 25% is enough to hide the real number on a site with twenty visits.
How blocking works matters more than the numbers, because it tells you what to do. Blockers use lists of domains. google-analytics.com is on all of them. So is the address of every hosted analytics service that is popular enough. EasyPrivacy, the most widely used privacy blocklist, names umami.is, goatcounter.com, counter.dev and cloudflareinsights.com, and blocks each of them whenever it loads on someone else's site. A server you set up yourself is on no list at all. It isn't hidden. Nobody has ever had a reason to add it.
So the solution for honest numbers is the same as the solution for no banner: run the tracker yourself. Both hard requirements depend on how the tracker is delivered, not on what the product can do.
The options, side by side
With the two hard requirements defined, the table below mostly decides itself.
| Option | Sites it can cover | Single dashboard | Consent banner | Survives blockers | Usable history |
|---|---|---|---|---|---|
| Vercel Web Analytics | |||||
| Umami Cloud (Hobby) | |||||
| Cloudflare Web Analytics | |||||
| GoatCounter (hosted) | |||||
| GA4, one property | |||||
| counter.dev | Not published | ||||
| Umami, self-hosted |
Each option that I rejected fails on a specific cell of that table.
Vercel Web Analytics comes first because I already pay for it. It uses no cookies. It recognises visitors with a hash of the request that changes every day, which can't be linked across days or across sites. Its script loads from the site's own domain, so it's the most first-party option on this list. And it's useless for me. Turning it on adds routes under /_vercel/insights/* to your next deployment, and the script can only send data to that deployment. Sixteen of my seventeen sites are on GitHub Pages, so they have no Vercel deployment to add the routes to. No paid plan changes this, because it isn't a limit of the plan but the way the product is built.
Umami Cloud is the same software I ended up running, and its Hobby plan is generous: 100,000 events a month and all the reports. It covers a single website. Seventeen sites don't fit in one, and liking the product doesn't change that.
Cloudflare Web Analytics looked like the best free option, and it fails both hard requirements. The documented limit is ten sites that don't use Cloudflare as their proxy. Support can raise that limit, but I would start at ten for seventeen sites. More importantly, the frequently asked questions (FAQ) page says it keeps the full data for seven days, and after that it's "aggregated down to around 10%". Cloudflare keeps a bigger share for sites with little traffic, so this is less bad than it sounds. But the question I care about most, this year compared with last year, would still be answered from an estimate. And the script comes from a third-party domain that blockers already know.
GoatCounter is a good and honest project, and its hosted service is free for reasonable public use. The homepage says clearly that a personal site or a small or medium business is fine. The problem is how it's designed, not its price. GoatCounter doesn't record the domain, so tracking several sites means creating one separate site for each, each with its own dashboard. Seventeen dashboards is exactly what the one-dashboard requirement is there to prevent.
GA4 as a single property fails worst, and it costs the most work. It needs a consent banner in four different codebases before the first number appears. For this audience, it's the most blocked script on the web. Free properties keep event data for fourteen months at most, which is barely enough to compare one year with the one before. And a property that covers seventeen domains is the cross-site tracking that the AEPD exception rules out.
counter.dev came second. It uses no cookies, you pay what you want, and it has no limits. It loses on smaller points. It shows few metrics, on purpose. Its script comes from someone else's domain, so blocklists include it. And I couldn't find a published rule on how long it keeps data. That's uncomfortable when the data has to show a trend over several years.
Why self-hosting the same tool changes the answer
Look at what actually ruled out Umami Cloud: a one-site limit and a third-party domain. Neither comes from the software. Both come from where it runs. Umami is open source and you can host it yourself. Running it yourself removes both problems and keeps everything that made it attractive.
Hosted by me, it meets all four requirements at once. It has unlimited websites and one dashboard with every hostname. History expires when I decide, not when a plan says so. And the tracker is served from analytics.pearpages.com, which is on no blocklist.
"First-party" does less here than it seems, so it's worth being precise. analytics.pearpages.com is first-party only for the sites under pearpages.com. For the other six root domains, it's a request to somebody else's domain, and the browser treats it as third-party. What really helps is something else: no blocklist knows the host, and the request carries no cookie that a browser could remove. I could set up seven tracker subdomains, one per root domain. That would recover the last few percent of visits, but with seven times the setup and seven certificates. I chose the simpler design, and I accept this weakness in it on purpose.
The consent position is also better than "exempt". Umami's documentation says clearly that the tracking code uses no cookies. The script itself confirms it. It never writes to browser storage. It only reads one item, umami.disabled, which exists so that a visitor can turn the tracker off for their own browser.
To count unique visitors, the server calculates an identifier instead. The identifier is a hash of the website's own identifier, the visitor's Internet Protocol (IP) address, the user agent (a line of text that names the browser and system) and a salt that changes once a month by default. A hash turns these inputs into a fixed code, and nobody can work backwards from the code to the inputs. The website identifier is part of the input. So the same person on two of my sites gets two unrelated identifiers, and they can't be joined. I don't have to remember a setting for this. The data model itself meets the AEPD's fourth condition.
Two practical points about the script. It's small: 2.3 kB, compressed with gzip. And it watches the browser's pushState and replaceState functions, so it notices when a single-page application (SPA) changes the page address without a full reload, so the plain script tag records those page changes with no code for a specific framework.
One more precise point, because it matters. Article 5(3) covers reading information on the device, as well as storing it, so that one localStorage read is technically covered by the rule. But the visitor sets that item themselves, to turn tracking off. That is clearly "strictly necessary for a service the user requested". I'm comfortable with it. Another site owner's lawyer might still want a sentence about it in the privacy policy.
No cookies means no banner, but you still have to inform people
I didn't expect this part. A tool that needs no consent banner saves you the work of building a banner: the component, the storage, the four codebases. It doesn't save you the legal work. The legal work moves somewhere else.
Three of the sites publish cookie policies, and all three become wrong as soon as the tracker is added. The worst one is on a tax-advice firm's site. Its policy says, in Catalan, that the site loads no external resources that track your browsing. Add the tracker and that sentence is false, on a live legal page of a professional firm. The second policy says the site uses no analytics cookies. That stays true, because Umami sets none, but it doesn't mention the measurement at all. The third names Vercel Analytics and Google Analytics and says they need consent. That describes neither what the site does today nor what it will do next.
None of this is optional, and the AEPD guide explains why: the exception from consent comes with a duty to inform. So the order of work is fixed. The new policy text and the script tag go live in the same change, in every language. A tracker without cookies, on a site whose policy says there is no tracking, is worse than an honest banner.
So the correct claim is this: going cookieless removed the biggest part of the work, not the biggest part of the responsibility.What it actually costs
Nothing is free, so here are the real costs.
- About thirty minutes, once. A Postgres database, a fork (my own copy of the Umami code on GitHub), a deployment and a subdomain. After that, it's done.
- A new deployment a couple of times a year. When I copy the latest Umami code into my fork, Vercel rebuilds the app, and the database updates run during the build. This is the regular cost of owning the server instead of renting it.
- A separate database, not a table inside an existing one. Neon's free plan gives 100 compute-hours and 0.5 GB of storage per project. When the storage is full, the database stops accepting writes. If the analytics tables lived in the Neon project of a real app, full analytics tables could stop that app from saving data. With a separate project, the worst case is one broken dashboard.
- Two limits worth knowing before you reach them. In my database, Umami uses roughly 200 bytes per pageview, and it never deletes old data on its own. So 0.5 GB holds about 2.5 million pageviews. That is years away, but not never. For compute, at the smallest Neon size (0.25 compute units), the 100 compute-hours last about 400 of the ~730 hours in a month, and every pageview keeps the database awake for another five minutes. So the compute limit only matters with constant traffic, roughly one visit every five minutes for more than thirteen hours a day. Both limits are far away. Both go in the project's README (its main documentation file) with a yearly reminder, because when you forget a limit, the tracker just stops counting and nothing tells you.
- A spending alert, never an automatic pause. The dashboard runs on a Vercel Pro team that I already pay for another project, so it adds no new subscription. Pro also allows commercial use, so the business sites are allowed there, which the free Hobby plan wouldn't allow. Pro charges for extra use instead of stopping the service, which is the right choice. But the spending limit must be an alert a few dollars above the monthly credit, never the automatic pause. An automatic pause stops projects, and stopping a real app with real users to save a few dollars of analytics would be an outage I caused myself.
- A slow first event after a quiet period. On the free plan, the database shuts down after five minutes without activity, and you can't turn that off. These sites are quiet, so the database is usually asleep. The first event after a long quiet period may arrive while it's still starting. Losing an event now and then is acceptable for a database that costs nothing.
Choosing a region in the EU (eu-central-1) keeps the data in Europe. That avoids all the legal questions about sending personal data outside the EU.
How the pieces fit together
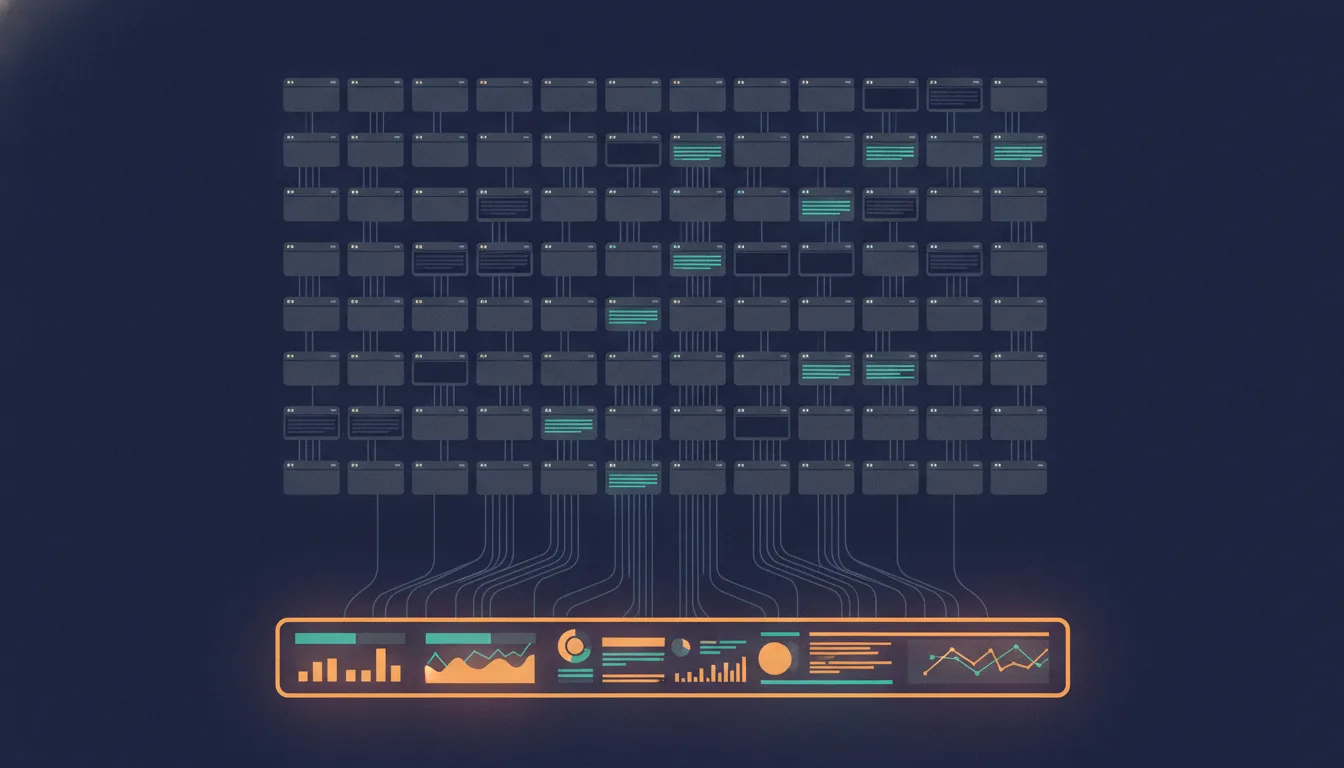
The design has three parts and one subdomain.
The tag is the same on every site, except for the identifier:
<script defer src="https://analytics.pearpages.com/script.js" data-website-id="UUID-HERE"></script>
There is one universally unique identifier (UUID) per hostname, not per repository. This matters in one place. A group of promotional pages for browser extensions all live on one hostname, each under its own path. So they are one website in Umami and several rows in its Pages report, which is exactly the right level of detail.
The tag goes into three kinds of place. The first kind is why seventeen sites are less work than they sound:
| Kind of site | Sites | Where the tag goes |
|---|---|---|
| Shared Astro layout | 6 | One </head> edit per codebase, covering every page |
| Plain static HTML | 9 | One line in each index.html |
| Framework config | 2 | The Docusaurus headTags array; the Next.js root layout <head> |
Checking that the tag is really there needs care, because when it's missing, nothing tells you. Looking at the source code proves nothing, because build steps remove and rewrite things. The check that counts is to download the live page with curl and search the published HTML for the analytics hostname. If a site shows zero visits after you've visited it yourself, the tag almost always never made it into the built site. It doesn't mean nobody came.
Two results look like errors but aren't. One site, a small demo of reactive programming, loads, but the only script it needs returns a 404 error, because that file is excluded from Git and never built. I added the tag anyway, so the pageview count can tell me whether anyone visits a broken page. Another site uses a service worker (a script that saves pages in the browser for offline use) that has saved its own index.html. Returning visitors won't get the tag until the service worker updates. Expect a delay there, not an error.
Keeping Google Analytics on this blog, on purpose
This blog is the one exception. It keeps GA4 and gets Umami too, both running at the same time, and its consent banner stays as it is. GA4 writes cookies, so the banner has to stay anyway.
That looks like doing the same work twice, and it's on purpose. On this one site, the difference between the GA4 number and the Umami number measures how many visits GA4 misses for my readers, not for Plausible's sample or for an industry average. After a few months, that difference is the evidence I need to decide whether GA4 and its banner are worth keeping at all.
Everything else is left out on purpose: this measures website visits only. Package downloads, repository stars and extension installs are all interesting, but they live in other systems and belong to a different project. The question was whether anyone looks at these sites. Seventeen script tags and one subdomain later, I have an answer.
References
- Directive 2002/58/EC (ePrivacy) — EUR-Lex
- Ley 34/2002 (LSSI), Art. 22.2 — BOE
- AEPD, Guía: Uso de cookies para herramientas de medición de audiencia (January 2024)
- Plausible, 58% of Hacker News, Reddit and tech-savvy audiences block Google Analytics
- Umami — pricing and plan limits
- Umami — documentation FAQ (cookies and privacy)
- umami-software/umami — source and self-hosting requirements
- Cloudflare Web Analytics — limits
- Cloudflare Web Analytics — FAQ on sampling and retention
- GoatCounter — free use and pricing
- GoatCounter — tracking multiple domains and sites
- Google Analytics — data retention settings
- counter.dev
- Vercel Web Analytics — how visitors are determined
- Vercel Web Analytics — quickstart and the
/_vercel/insightsroutes - Neon — plans and free-tier limits
- EasyPrivacy — the full blocklist
- Umami — environment variables (salt rotation)