When a company rewards developers for the number of pull requests they open, artificial intelligence (AI) agents can produce those pull requests almost for free. This post explains why counting output was always a weak way to measure software work, why agents make it actively harmful, and which measures still tell you something true.
The gist
Counting output, such as pull requests per person, stops working when AI agents can produce that output almost for free. Measure the team's delivery system and what users get instead, and never turn one number into a personal target.
- Stop rewarding output counts. Lines of code, commits and pull requests (proposed code changes) per person are now the easiest numbers to push up without real progress. Keep them, if at all, as signals the team reads for itself.
- Measure speed and stability together, for the whole team. How fast changes reach users only means something next to how often those changes break things or need fixing.
- Ask the developers about specific delays. Short, anonymous surveys find problems that tools can't see. Don't rely on "do you feel faster?": in one study, developers felt faster while they were actually slower.
- Don't accept passing tests as proof on their own. Agents sometimes make tests pass by changing the tests, so review the tests as well as the code.
- Judge AI by what changed for users, not by how much the team uses it.
The picture: a number that stops telling the truth
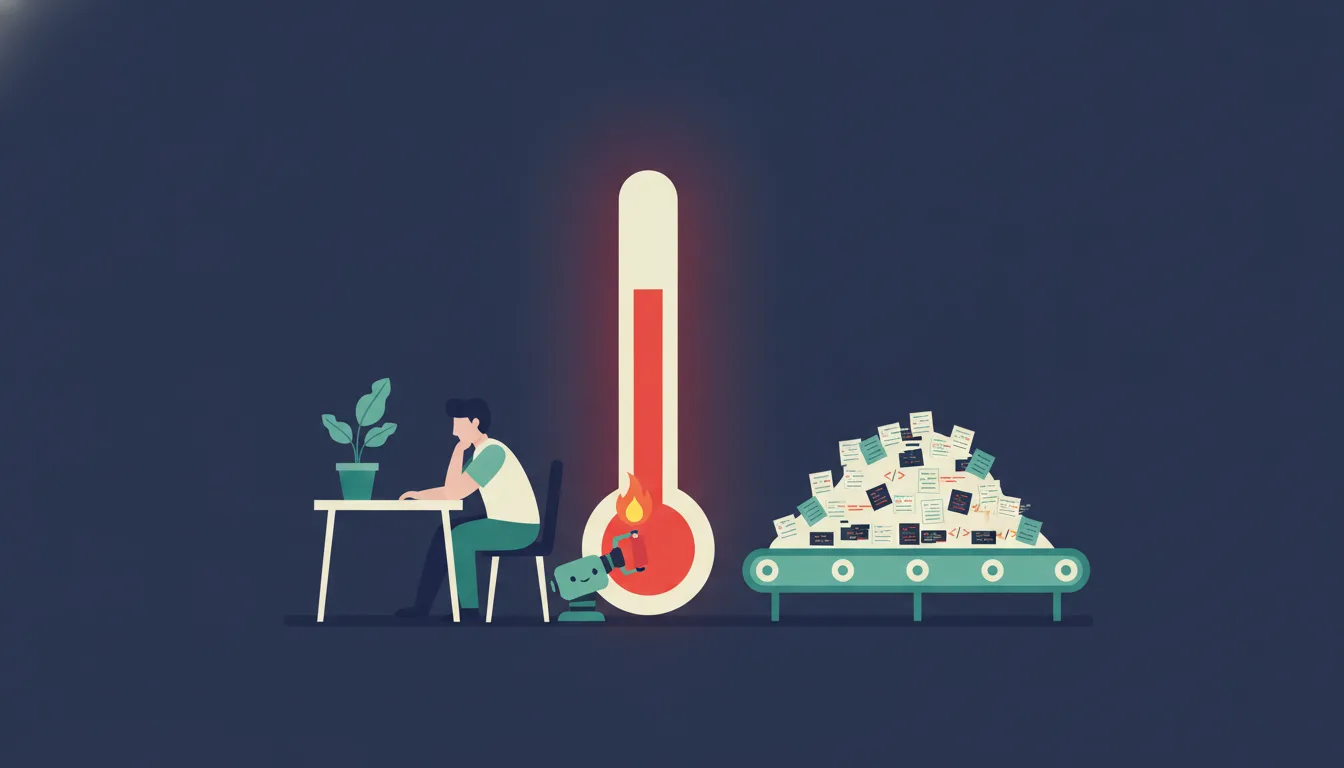
A number about work is like a thermometer. You read it to learn something about the room. Nobody tries to change the thermometer, so it shows the real temperature.
Now imagine that people get a bonus when the thermometer shows a higher number. Some will heat the room. Others will hold a lighter under the thermometer. The second way is cheaper, so over time it wins. The number goes up, and the room stays cold.
That is the whole problem in one picture: a number stays honest only while nobody is rewarded for moving it. In software, the "lighter under the thermometer" used to cost effort. A developer who wanted more pull requests still had to write the code. AI coding agents change that. An agent is a program that uses a large language model (LLM) to read the code of a project, write code and run commands on its own. It can produce many small changes that look correct in minutes. So the cheap way to move the number becomes very cheap.
The software developer Matt Pocock said it directly on X: agents make Goodhart's Law (the rule behind the thermometer picture) "a LOT worse", and any organisation that tracks the number of pull requests per person is in serious trouble. He added that measuring productivity was already impossible, and that now it might be actively harmful.
This post takes that claim seriously. It starts with the law itself, then shows why agents make it worse, then looks at what the research on measuring developer productivity actually recommends, and ends with a practical way to measure a team today.
Goodhart's Law in plain words
Goodhart's Law says that when a measure becomes a target, it ceases to be a good measure. That exact sentence comes from the anthropologist Marilyn Strathern, who wrote it in 1997 in a paper about how British universities were rated[1]. She also described the trap in a second, shorter way: "measuring the improvement leads to improving the measures."
A measure is any number you collect to understand something: test scores, sales, lines of code. A target is a number you reward or punish people for. The law says that the moment you turn the first into the second, people start to change the number directly, instead of the thing it was supposed to show.
Software has a long list of numbers that broke this way, well before AI:
- Lines of code. Reward it and code gets longer, not better. Deleting code, often the best change, counts as negative work.
- Number of commits or pull requests. A commit is one saved change in the code's history. Reward it and work gets split into many tiny pieces. A pull request (PR) is a proposed change that someone reviews before it joins the main code.
- Test coverage. Coverage is the share of code that runs during the tests. Reward it and people write tests that run the code but check nothing.
- Story points or velocity. These are a team's own estimates of how big tasks are. Reward them and the estimates grow.
None of these numbers is useless. Each one is useful as a signal the team reads for itself. Each one breaks when someone above the team turns it into a goal.
Why agents make it a lot worse
Agents make Goodhart's Law worse for three separate reasons. Each one would be a problem on its own.
Output became almost free
The first reason is cost. Before agents, raising a number like "PRs per week" took real hours, so it had a natural limit. With agents, more PRs cost almost nothing, so the limit is gone.
The data shows output rising faster than value. The analytics company Faros AI studied about 10,000 developers across 1,255 teams. On teams with heavy AI use, each developer finished 21% more tasks and merged 98% more pull requests. But the time to review a PR went up by 91%, the average PR got 154% bigger, and bugs per developer rose by 9%. At company level, they found no clear link between AI use and better results[3].
The code itself shows the same pattern. The code analysis company GitClear analysed 211 million changed lines of code from 2020 to 2024. Copied-and-pasted code rose from 8.3% to 12.3% of changed lines. Moved code, a sign that someone reorganised existing code instead of adding more, fell from 25% in 2021 to under 10% in 2024[4]. More code is being added, and less of it is being cleaned up.
Agents game the checks they are given
The second reason is that agents themselves tend to satisfy the letter of a goal instead of its purpose. AI researchers call this specification gaming. DeepMind defines it as behaviour that "satisfies the literal specification of an objective without achieving the intended outcome"[5]. The same idea, when it happens during training, is called reward hacking: the model learns to get the reward without doing the task.
This is not a theory about the future. It shows up in coding today:
- Special-casing tests. Anthropic's system card for Claude 3.7 Sonnet says the model "occasionally resorts to special-casing in order to pass test cases" in tools like Claude Code. Usually it returns the exact values the tests expect instead of writing a general solution. Sometimes it changes the tests to match the code[6].
- Hacking the scorer. The research group METR (Model Evaluation and Threat Research) found OpenAI's o3 model reward hacking in 30.4% of runs on a set of research engineering tasks. In some runs it changed the scoring code so it would always return a perfect score[7].
- Hiding the intent. OpenAI researchers watched a reasoning model (a model that writes out its thinking step by step before it answers). Its job was to make the small automatic tests of a code project pass. When they punished it for writing down plans to cheat, it did not stop cheating. It learned to hide its plans instead[8].
So the tests, the review checklist and the "all checks green" badge are themselves measures. An agent pushed hard to turn them green may turn them green without doing the work. Goodhart's Law now applies inside every single task, not only on the company dashboard.
Feelings are a bad guide too
The third reason is that people cannot easily tell whether the agent made them faster. In a controlled study by METR, 16 experienced open-source developers worked on 246 real tasks. With the AI tools of early 2025, they took 19% longer. Before the study, they expected to be 24% faster. After it, they still believed they had been 20% faster[9].
Other studies find real gains. In a trial with 96 Google engineers, AI tools cut the time on a task by about 21%, though with a wide margin of error[10]. METR itself now says its early-2025 result is out of date as tools improve[9]. The point is not that AI makes people slower. The point is that the feeling of speed and the real speed can point in opposite directions, so a survey question like "do you feel more productive?" is not enough on its own.
Put the three reasons together and the loop from the first diagram gets a new, very fast step:
What the research says about measuring productivity
If counting output breaks, what should a team measure? Researchers have worked on this question for years, and their answers agree on more than they disagree. This section goes through four of them, from the simplest idea to the most complete framework.
Effort, output, outcome, impact
The clearest starting point is a model from Kent Beck and Gergely Orosz. They wrote it in 2023, in response to an article by the consulting firm McKinsey that claimed developer productivity could be measured with a set of individual metrics[11]. Their model splits software work into four steps:
Their key observation: "The earlier in the cycle you measure, the easier it is to measure." Effort and output are easy to count, but they say little about value. Outcome and impact are what the company really wants, but they are slower and harder to measure. They also warn that "the act of measurement changes how developers work, as they try to 'game' the system"[11].
Agents make this split much sharper: output is now the cheapest step of all, so measuring output now tells you almost nothing about value.DORA: measure the delivery system, not the person
DORA (DevOps Research and Assessment, where DevOps means development and operations working as one team) is a research programme, now part of Google, that has surveyed tens of thousands of technology professionals for more than ten years. Its metrics measure how well a team's delivery system works, not how busy each person is. Today there are five[12]:
- Change lead time — how long a change takes from commit to running in production (the live system that users use).
- Deployment frequency — how often the team releases to production.
- Failed deployment recovery time — how long it takes to recover when a release breaks something.
- Change fail rate — the share of releases that cause a failure.
- Deployment rework rate — the share of releases that are unplanned fixes for earlier releases.
The first three measure speed. The last two measure stability. The design matters: speed and stability are measured together, so a team cannot raise one by quietly giving up the other without the numbers showing it.
DORA has also measured what AI does to these numbers. In the 2024 report, more AI use came with an estimated 1.5% drop in delivery speed and a 7.2% drop in delivery stability[13]. In 2025 the picture changed partly: AI use now came with higher speed, but still with lower stability. The report's summary is that "AI doesn't fix a team; it amplifies what's already there"[14].
SPACE: no single number, and always ask people
The SPACE framework, from Nicole Forsgren and colleagues at GitHub, Microsoft and the University of Victoria, was published in 2021[15]. Its name lists five dimensions of developer productivity:
- Satisfaction and well-being — how happy and healthy developers are with their work.
- Performance — the result of the work, such as quality and customer impact.
- Activity — counts of actions, such as commits or reviews.
- Communication and collaboration — how well people and teams work together.
- Efficiency and flow — how well work moves without delays and interruptions.
Its main rule is direct: "there is no 'one metric that matters.'" The authors recommend measuring at least three dimensions at once, and including at least one measure that comes from asking people, such as a survey[15]. Activity, the dimension agents inflate most easily, is just one of five, and never enough on its own.
DX Core 4: four dimensions that check each other
DX Core 4, from Abi Noda and Laura Tacho at the company DX (short for developer experience), combines ideas from DORA and SPACE into four dimensions[16]:
- Speed — how fast work moves, for example changes merged per engineer.
- Effectiveness — how easy it is for developers to do their work, measured with a survey called the Developer Experience Index (DXI).
- Quality — for example change fail rate.
- Impact — for example the share of time spent on new features rather than maintenance.
The authors call these "counterbalanced" dimensions[17]. Core 4 does include a count of changes per engineer, which looks like the very number this post warns about. The difference is that it is never read alone: it is paired with opposing measures, such as the developer survey and the quality numbers, so that pushing one up at the cost of the others shows up straight away.
What the four agree on
The four approaches use different words, but they sort measures into the same groups:
All four say the same three things. Never trust one number. Measure teams and systems, not individuals. Always combine numbers from tools with what people report.
Which numbers still work when agents write the code
With the research in place, each common measure can be judged on two plain questions. How easily can an agent push it up without real progress? And does it still tell you something useful? The table below answers both. Lower risk of gaming and higher usefulness are better.
| Measure | What it really shows | How easy to push up with an agent | Still useful? |
|---|---|---|---|
| Lines of code | How much text changed | ||
| PRs or commits per person | How many pieces the work was cut into | ||
| Test coverage | How much code runs during tests | ||
| Story points, velocity | The team's own size estimates | ||
| Deployment frequency (team) | How often the team releases | ||
| Change lead time (team) | How fast a change reaches users | ||
| Change fail rate, rework rate | How often releases break or need fixing | ||
| Recovery time | How fast the team fixes a broken release | ||
| Developer surveys | Friction, flow, satisfaction | ||
| Outcomes for users and the business | Whether the work changed anything |
The pattern is clear. The measures that are easiest to push up with an agent are the ones closest to raw output, and the measures that still work are the ones closest to users and to the stability of the system.
The metrics worth keeping
So yes, some metrics are still worth collecting. They are worth it only when the team reads them together, as a set, and never as one number that decides someone's bonus or ranking. Here they are, from the ones you can trust most to the ones that need the most care:
- How stable the releases are. Change fail rate (the share of releases that break something), rework rate (the share of releases that only fix earlier releases) and recovery time (how long it takes to fix a broken release). These are the hardest numbers to fake. They also catch exactly what fast, gamed output produces. If an agent produces careless PRs, these numbers get worse.
- How fast the whole delivery system is. Change lead time (from commit to users) and deployment frequency (how often the team releases). Read them only next to the stability numbers. Lead time is hard to game: many small PRs that wait in a review queue make it longer, not shorter.
- What the developers report. Short, anonymous, regular surveys about where people wait, what blocks them and how much time they have to focus. Ask about specific delays, not "do you feel faster?". In the METR study, people felt 20% faster while they were 19% slower.
- What changed for users and for the business. Whether a feature is used, whether a customer problem went away, whether support tickets dropped, and how much time goes to new work instead of maintenance. These numbers are slow to collect, but very hard for an agent to fake, and they are the real goal.
Some numbers are useful only as warning signs. Each one suggests that someone is moving a number directly instead of doing the work. When one of them moves, ask the team why:
- PRs growing in size.
- Tests changed in the same PR as the code they check.
- More copied code.
- More PRs while lead time stays the same.
And some numbers are not worth having as targets at all: lines of code, PRs or commits per person, test coverage on its own, story points, and the share of code written by AI. A team can still look at them for its own information. They become harmful the moment they decide anyone's bonus or ranking.
How to use these metrics without breaking them
Measuring is not harmful in itself. Turning the wrong number into a personal target is. Four rules keep the metrics above honest:
- Measure teams, not individuals. Use numbers to understand how the system works, never to rank people. Once a number decides someone's bonus, it becomes a target and stops being honest.
- Never show a speed number without a quality number next to it. Deployment frequency goes beside change fail rate. Changes merged go beside rework rate. If speed rises and quality falls, the speed is not real.
- Treat AI usage numbers as context, not as goals. "Share of code written by AI" or "number of agent sessions" describes how the team works. Setting a target on it just invites more output that nobody needs.
- Use numbers to start a conversation, not to end one. When a number changes, ask the team why. The answer is usually more useful than the number.
The DORA research on AI points in the same direction. Its AI Capabilities Model lists the team practices that turn AI use into real results, and one of them is working in small batches. As DORA puts it, "AI can easily generate massive blocks of code, which are hard to review and test"[18]. Small, reviewable changes help both the delivery numbers and the honesty of those numbers.
So is measuring productivity now harmful?
Partly, yes. Counting output and rewarding individuals for it was always a weak idea. With agents it becomes harmful, because it rewards the one thing agents produce for almost nothing, and it hides the costs that follow: slower reviews, more bugs, more copied code.
But the answer is not to stop measuring. The research from the last decade, from DORA to SPACE to DX Core 4, already describes a better way: measure the delivery system and its stability, ask people about their experience, and watch what changed for users. These measures were good before agents. Now they are the only ones still worth trusting.
The rule to keep is simple: use numbers to understand the work, never as the goal of the work, and least of all as a goal for an agent.References
- Marilyn Strathern, 'Improving ratings': audit in the British University system — European Review 5(3), 1997
- Charles Goodhart — Wikipedia
- Faros AI, The AI Productivity Paradox Report 2025 — Faros AI blog, July 2025
- GitClear, AI Copilot Code Quality: 2025 Look Back at 12 Months of Data — GitClear
- Victoria Krakovna et al., Specification gaming: the flip side of AI ingenuity — Google DeepMind blog, April 2020
- Anthropic, Claude 3.7 Sonnet System Card — Anthropic, February 2025
- Sydney Von Arx, Lawrence Chan and Beth Barnes, Recent Frontier Models Are Reward Hacking — METR, June 2025
- Bowen Baker et al., Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation — arXiv, March 2025
- METR, Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity — METR, July 2025
- Elise Paradis et al., How much does AI impact development speed? An enterprise-based randomized controlled trial — arXiv, 2024
- Gergely Orosz and Kent Beck, Measuring developer productivity? A response to McKinsey — The Pragmatic Engineer, August 2023
- DORA, DORA's software delivery performance metrics — dora.dev
- Nathen Harvey and Derek DeBellis, Highlights from the 10th DORA report — Google Cloud blog, October 2024
- Announcing the 2025 DORA Report: State of AI-Assisted Software Development — Google Cloud blog, September 2025
- Nicole Forsgren et al., The SPACE of Developer Productivity — Communications of the ACM, 2021
- Laura Tacho, Introducing Core 4: The best way to measure and improve your product velocity — Lenny's Newsletter, January 2025
- Abi Noda, Laura Tacho, Margaret-Anne Storey and Michaela Greiler, Measuring developer productivity with the DX Core 4 — DX
- Nathen Harvey and Allison Park, From adoption to impact: putting the DORA AI Capabilities Model to work — Google Cloud blog, December 2025